Good bug reproduction steps do one job: let a developer recreate the failure without asking a single follow-up question. The single highest-impact practice is writing 4 to 8 numbered steps from an explicit starting state, pinning expected versus actual behavior at the exact step that fails, and attaching a screenshot or recording whenever the environment matters. Get that right and most bugs get fixed on the first pass instead of bouncing back for clarification.
TL;DR:
- Clear, concise, numbered steps from a known starting state enable developers to reproduce bugs on the first attempt, reducing fixing time.
- Four to eight steps at the right level of detail prevent confusion and unnecessary clarification cycles, especially for environment or race condition bugs.
- Attaching environment details and multiple forms of evidence, such as session replays or logs, dramatically improves reproducibility and diagnosis.
- Reproducibility rate, along with precise failure signatures, helps distinguish deterministic bugs from flaky issues, guiding effective resolution strategies.
- Using automated tools like Wezard that record and transcribe bug reports in real time streamlines reproduction, captures critical details, and minimizes duplicate tickets.
Table of Contents
- Why Clear Bug Reproduction Steps Matter
- How Do You Write Reproducible Bug Steps?
- What Environment Details and Evidence Should You Attach?
- How Do You Handle Intermittent or Non-Reproducible Bugs?
- A Copy-Paste Template and Checklist for Reproduction Steps
- Common Mistakes That Break Otherwise Good Bug Reports
- When Written Steps Aren’t Enough: Capture and Session Replay
- Perspective: Making Reproduction Discipline a Team Habit
- How Wezard Closes the Gap Between Steps and Evidence
- Sources
- FAQ
Why Clear Bug Reproduction Steps Matter
A bug report lives or dies on one field more than any other. Steps to reproduce carry more weight than the title, the severity tag, or even the stack trace, because a developer who can trigger the failure on the first try fixes it faster than one who has to guess at what you did. BugMojo’s guidance on bug reports identifies six fields that make a report actionable: title, steps to reproduce, expected versus actual results, environment, evidence, and a severity signal. Steps to reproduce sit at the center of that list because first-try reproduction is the strongest predictor of how fast a fix ships.
When steps are vague, the cost shows up as delay, not failure. A ticket that says “checkout sometimes breaks” doesn’t get triaged. It gets bounced back with a comment asking which browser, which account, and what “sometimes” means. Multiply that by a QA team filing dozens of tickets a week and the hours lost to clarification cycles add up fast.
Reproductions also do something less obvious: they tell triagers whether a bug is device-specific or environment-specific before anyone even opens a debugger. Test IO’s documentation on bug reproductions notes that reproduction attempts often come back “positive,” “negative,” or “different bug,” and that pattern alone helps estimate severity and scope. A bug that reproduces on one device and not another is a different engineering problem than one that fails everywhere.
Steps alone aren’t always enough, though. Three situations tend to break the pure prose approach:
- Intermittent bugs that only fail some percentage of the time
- Environment-dependent failures tied to a specific OS, browser build, or network condition
- Race conditions and timing bugs where the “step” that matters happens in milliseconds
In those cases, written steps still matter for triage speed, but they need backup: a recording, a log, or a replay that captures what prose can’t.
How Do You Write Reproducible Bug Steps?
Getting reproduction steps right is less about writing skill and more about discipline: pick the right altitude, keep the count tight, and always pin expected against actual at the point of failure. BugMojo’s steps-to-reproduce guide frames this as four rules working together: correct altitude, an explicit known starting state, expected versus actual pinned at the failing step, and the right granularity.
Pick the right altitude
Altitude is the level of detail you write at, and most bad reproduction steps fail here before anything else. Too high, and you write “log in and try to check out,” which skips the actual trigger. Too low, and you narrate every mouse movement and keystroke, burying the one action that matters in noise a developer has to wade through.
The right altitude describes each user-facing action a developer could actually perform: click this button, enter this value, select this option. Skip internal implementation details you can’t observe from the UI, and skip cosmetic details that don’t affect the outcome. If you wouldn’t personally read step 3 of someone else’s ticket without skimming, it’s probably at the wrong altitude.
Keep steps to a tight numbered list
Four to eight steps is the useful range, and it’s not arbitrary. Fewer than four steps and you’ve probably skipped a piece of required state, something the developer will hit a wall trying to fill in. More than eight and one of two things has usually gone wrong: you’re describing at the wrong altitude, or you’ve actually bundled two different bugs into one ticket.
Write the sequence as a numbered list, one action per line, never two actions crammed into a single step:
- Log in as a seeded test account (
qa_test_042@example.com). - Navigate to
/checkoutwith three items already in the cart. - Apply promo code
SAVE20at the cart summary screen. - Click “Continue to Payment.”
- Select “Credit Card” as the payment method.
- Enter a valid test card number and click “Place Order.”
That’s six steps, each one a single, observable action. Anyone on the team could execute that sequence without asking what “checkout” or “the usual account” means.
Pin expected versus actual at the failing step
The step where things go wrong needs two extra lines directly attached to it, not buried in a separate paragraph. Write it as:
Expected: Order confirms and the promo discount reflects in the total.
Actual: Order confirms, but the total still shows the pre-discount price.
Attaching expected and actual right at the failing step, rather than at the top of the ticket, removes the ambiguity that causes “works as designed” disputes. The developer sees exactly where reality diverged from the spec, not a general complaint about checkout being broken.
Anchor an explicit starting state
Every reproduction needs a known zero point. That means naming the account you used (ideally a seeded test account created specifically for QA, not your personal login with unknown cart history), the exact URL you started from, and the state of any feature flags that might change behavior. “Log in and go to settings” assumes the reader knows which account, which environment, and which flags are on. State it instead: “Using account qa_seed_17, with the new_billing_ui flag enabled, navigate directly to /settings/billing.”
Pro Tip: Always test the reproduction in an incognito or private window before filing the ticket. If the bug disappears, you’ve just found a caching or session state dependency that belongs in your steps, not in the developer’s inbox as a mystery.
What Environment Details and Evidence Should You Attach?
Steps tell a developer what you did. Environment and evidence tell them what conditions made it possible, and that distinction decides whether a bug gets reproduced in five minutes or five hours.
Environment fields worth including every time:
- App build number or commit SHA
- Operating system and version
- Browser and version (or app version for native apps)
- Device model, especially for mobile or responsive bugs
- Screen size or viewport dimensions
- Network condition, when the bug touches anything latency-sensitive
Atlassian and Mozilla’s longstanding bug-filing guidance, echoed in BugMojo’s reporting framework, treats exact build and OS version as non-negotiable because plenty of bugs are environment-specific in ways that aren’t obvious until someone tries to reproduce on a different setup and can’t.
Evidence is where most tickets fall short, mostly because testers default to one format regardless of the bug type. Match the evidence to what the bug actually needs:
- Screenshot: best for static UI bugs, like misaligned layouts or wrong text, where a single frame tells the whole story.
- Short video clip: best for interaction bugs, animations, or anything where the sequence of events matters more than any single frame.
- Session replay: best for anything environment-heavy or intermittent, since it captures the DOM, console, and network timeline together instead of just what the screen looked like.
- Console or network logs (HAR files): best for API failures, failed requests, or anything a visual recording won’t show, like a 500 response buried in a network call.
Reproducibility rate is the piece most tickets skip entirely, and it’s often the single most useful line in the report. Stating a consistent reproducibility rate versus a single occurrence with unclear pattern tells the triager immediately whether this is a deterministic defect that needs a fix or a flaky one that needs instrumentation first. Deterministic bugs get fixed faster because there’s no ambiguity about whether the fix actually worked. Flaky ones need a completely different investigation path, and mislabeling one as the other wastes everyone’s time.
How Do You Handle Intermittent or Non-Reproducible Bugs?
Flaky bugs punish anyone who tries to brute-force them with random retries. The fix is a disciplined, almost scientific process: define the failure precisely, rebuild the exact reported conditions, then change one thing at a time and record every result, including the times it didn’t fail.
- Write a precise failure signature first. Not “the app crashes sometimes” but “the checkout button becomes unresponsive after applying a promo code while on a throttled 3G connection.” Vague signatures make every later step harder because you’re chasing a moving target.
- Rebuild the reported conditions exactly. Same account type, same browser, same network throttle setting, same app build. Skipping this step is the most common reason intermittent bugs stay “unreproducible” for weeks.
- Run a control before changing anything. Reproduce once under the exact reported conditions to confirm you can trigger it at all, even once.
- Change one variable at a time. Swap the network condition, then the account, then the browser, testing each change in isolation. Guidance on AI-assisted bug reproduction recommends recording every pass and every fail during this process, since negative results narrow the hypothesis space just as much as positive ones.
- Capture a session replay during every attempt. For intermittent bugs, this matters more than for deterministic ones, because you may not get another shot at catching the failure live. A useful replay includes the DOM state, console output, network requests, and timestamps synced across all three.
- Report frequency, not certainty. Label the ticket clearly: “reproduced 3 of 5 attempts, always after the second promo code application” tells the developer far more than “sometimes happens.” A StackPractices template guide notes that mislabeling a genuinely intermittent bug as fully reproducible, or vice versa, is one of the fastest ways to lose a triager’s trust in the report.
Treat every measured attempt as data, not noise.
A Copy-Paste Template and Checklist for Reproduction Steps
The fastest way to raise the average quality of tickets across a QA team isn’t training everyone individually. It’s giving them a template they default to without thinking.
A minimal reproduction, the version stripped down to only what’s necessary to trigger the bug, is worth building deliberately rather than shipping your first working sequence. StackPractices’ method is straightforward: remove one step at a time and retest. If the bug still triggers, that step wasn’t necessary. Keep cutting until removing another step makes the bug disappear. What’s left is the minimal reproduction, and it’s the single highest-value piece of content you can hand an engineer.
Reproduction checklist:
- Known starting state named explicitly (account, URL, flags)
- Correct altitude, one observable action per step
- 4 to 8 numbered steps
- Expected versus actual pinned inline at the failing step
- Environment details attached
- Reproducibility rate stated
- Evidence attached (screenshot, video, or replay matched to bug type)
| Template Field | What Goes Here |
|---|---|
| Title | Short, specific: component + symptom (e.g., “Promo discount not applied at checkout confirmation”) |
| Steps to reproduce | 4 to 8 numbered actions from a known starting state |
| Expected → Actual | Inline at the failing step, two lines |
| Environment | Build/commit, OS, browser/version, device, network if relevant |
| Reproducibility | e.g., “5/5 attempts, two machines” or “3/5, intermittent” |
| Evidence | Screenshot, video clip, HAR, console log, or session replay |
| Severity | Blocker, major, minor, or cosmetic |
Example 1: UI checkout bug
Title: Promo code discount not reflected in order total
Steps: Log in as qa_seed_17 → add 3 items to cart → apply code SAVE20 at cart summary → continue to payment → select credit card → place order
Environment: Chrome 128, macOS 14.5, build 2026.09.14-rc2
Reproducibility: consistent attempts
Evidence: Screen recording, 12 seconds
Example 2: API bug
Title: /api/v2/orders returns 500 on second submission attempt
Steps: Authenticate with test token → POST valid order payload → POST identical payload again within 2 seconds
Expected → Actual: Second call should return 409 (duplicate) → Returns 500 with no error body
Environment: Staging, build 2026.09.10
Reproducibility: mostly consistent attempts
Evidence: HAR file with both requests and full response headers
Common Mistakes That Break Otherwise Good Bug Reports
The same handful of mistakes show up across most bounced tickets, and every one of them is fixable in under a minute once you know to look for it.
- Wrong altitude. Either too vague (“checkout is broken”) or too granular (narrating every click on the way to the actual trigger). Both waste a developer’s time in different directions.
- Unstated starting state. “Log in and try again” assumes shared context that doesn’t exist. Name the account, the URL, and any feature flags every time.
- No reproducibility measurement on flaky bugs. Filing an intermittent bug as if it’s deterministic (or vice versa) sends the developer down the wrong investigation path from step one.
- Hidden data dependencies. A bug that only appears with a cart that already has items, or an account with a specific subscription tier, needs that dependency stated explicitly, not assumed.
- Missing severity context. A cosmetic misalignment and a payment failure shouldn’t read the same on the page; flag which one you’re filing.
Pro Tip: Keep a small pool of seeded test accounts with known, stable states (empty cart, full cart, expired trial, active subscription) so nobody has to guess what state their personal account happens to be in when they file a bug.
When Written Steps Aren’t Enough: Capture and Session Replay
Written steps hit a ceiling with certain bug types, and pretending otherwise just produces longer and longer prose that still doesn’t help. Environment-heavy bugs, race conditions, and anything intermittent need a different kind of evidence: a timeline, not a description.
Session replay works as ground truth in these cases because it captures the DOM state, console output, and network activity together, synced to the same clock. A developer watching a replay doesn’t have to trust your description of what happened. They can see it, scrub back and forward, and check the console at the exact millisecond things went wrong.
A good replay setup for triage should include:
- The full DOM state at the moment of failure, not just a visual snapshot
- Console errors and warnings in the same timeline as user actions
- Network requests and responses, especially failed or slow ones
- Timestamps synced across all three so cause and effect are obvious
This is where a capture-first tool changes the workflow rather than just supplementing it. A capture-first tool records the screen, transcribes the issue in real time as the tester describes it out loud, and uses AI to flag likely duplicate tickets before they ever reach a backlog. Instead of a tester writing six steps from memory after the fact, the steps and the evidence get captured together, in the moment, which cuts down on the reconstruction errors that creep into reports written twenty minutes after the bug happened.
The rule of thumb: attach a short video clip when the bug is a one-off interaction issue, and reach for a full session replay when the bug is intermittent, environment-dependent, or involves multiple systems (UI, network, console) interacting in ways prose can’t cleanly describe.
Perspective: Making Reproduction Discipline a Team Habit
Most teams treat good reproduction steps as a skill some testers happen to have, rather than a template everyone defaults to. That’s backwards. The six-field structure, title, steps, expected versus actual, environment, evidence, severity, should be the literal default text that populates every new ticket in your tracker, not a standard people remember under pressure.
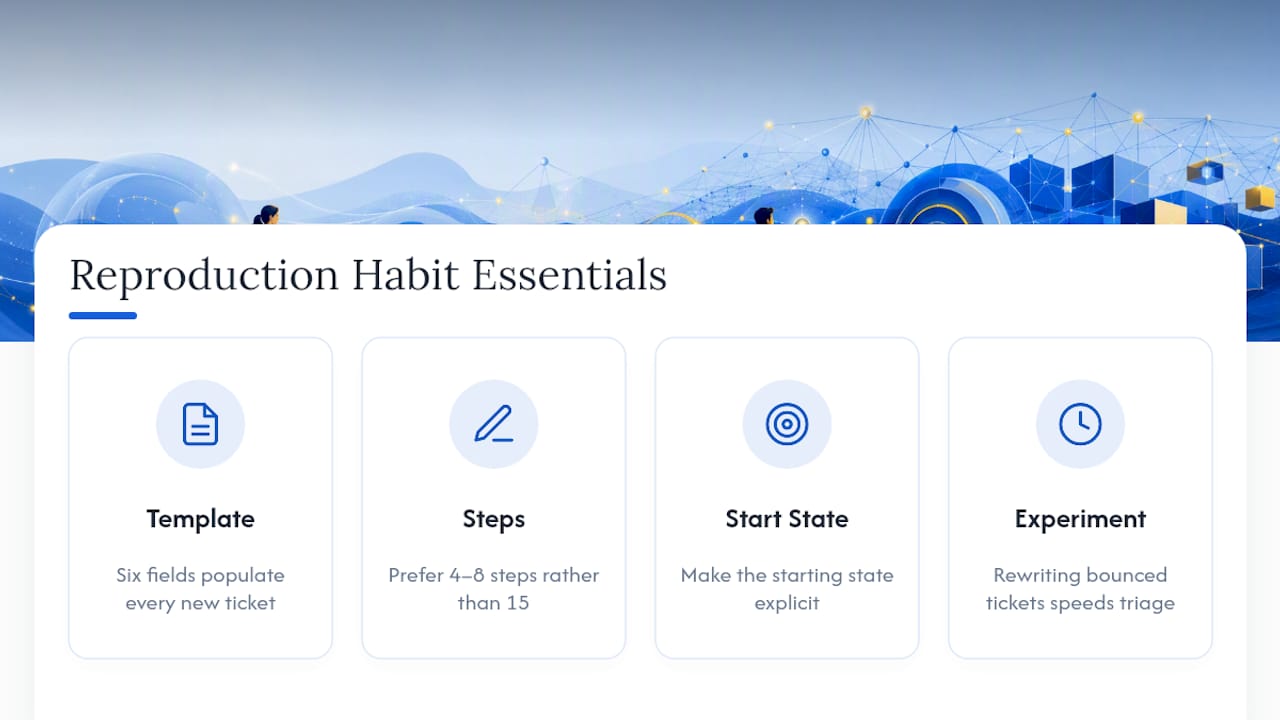
A useful experiment: pick a week’s worth of tickets that got bounced back for clarification, rewrite them using the template, and measure how much faster triage responds. The gap is usually larger than teams expect, and it makes the case for the template better than any policy memo would.
New testers should learn altitude and minimal reproduction before they learn tooling. A tester who understands why 4 to 8 steps beats 15, and why an explicit starting state matters, writes better tickets on any platform you hand them.
— Marketing
How Wezard Closes the Gap Between Steps and Evidence
Wezardapp is the alternative to reconstructing a bug report from memory: it records the screen, transcribes what the tester says as they say it, and flags likely duplicate tickets with AI before they clutter your Jira or Azure DevOps backlog.
That combination attacks the two biggest sources of friction in bug reporting at the same time. Testers stop losing detail between “I saw the bug” and “I wrote the ticket twenty minutes later,” because the steps and the evidence get captured in the same pass. And triagers stop wasting time re-reading five near-identical tickets about the same checkout failure, because duplicate detection catches the overlap before it ever hits the sprint board. Teams that adopt a capture-first workflow tend to see fewer clarification rounds and faster first-try fixes, exactly the outcomes the six-field template is designed to produce, without asking testers to write more.
If you’re evaluating how UAT feedback flows into your existing tracker, the Jira alternatives comparison for UAT and bug tracking is a reasonable next stop before you request a demo.
Sources
- How to Write a Bug Report That Actually Gets Fixed (2026) · BugMojo
- Bug Reproduction Steps Template | Doc | StackPractices
- Bug Reproductions
- How to Reproduce a Bug With AI · NewPrompt
FAQ
What Are the Steps to Reproduce a Bug?
Steps to reproduce are a numbered, 4 to 8 step sequence written from a known starting state, ending with the exact expected versus actual behavior at the point of failure.
What Are the Four Steps of Debugging?
Debugging generally follows reproducing the failure, isolating the minimal trigger, identifying the root cause, and verifying the fix against a regression test built from that same minimal reproduction.
What Are the Stages of the Bug Life Cycle?
A bug typically moves through new, triaged, in progress, fixed, and verified/closed, with reproducibility and severity determined during triage based on the reproduction steps and evidence attached.
How Do You Handle a Bug That Won’t Reproduce?
Define a precise failure signature, rebuild the exact reported environment, then change one variable at a time while recording every pass and fail as a measured frequency, rather than filing it as unreproducible.
Can Wezard Help With Reproduction Steps That Are Hard to Write?
Yes. Wezardapp captures screen recordings and transcribes issues in real time as testers describe them, which reduces the memory gaps that make written reproduction steps incomplete or inaccurate.