SOC 2 auditors do not accept a green dashboard as proof your team handles bugs correctly. They sample individual tickets and expect timestamps, an assigned owner, SLA adherence, remediation notes, and verification rescans covering the full observation period. A SOC 2 report is an attestation issued by a licensed CPA firm, and for Type II engagements, that firm is testing whether your process actually ran that way for months, not whether it looks good on paper today.
TL;DR:
- SOC 2 requires detailed ticket evidence including timestamps, owner, severity rationale, SLA adherence, and verification rescans for every vulnerability or incident.
- Auditors scrutinize past ticket data over several months, emphasizing consistent remediations and a continuous vulnerability management lifecycle.
- Backfilled tickets, missing investigation notes, or vague documentation significantly increase audit exceptions and should be avoided.
- Automated ticket creation and direct linkage of scan reports and verification evidence reduce human error and improve audit readiness.
- Conduct pre-audit exercises by exporting and reviewing ticket histories to identify and fix gaps before the formal audit process begins.
Table of Contents
- What SOC 2 expects from bug tracking and incident reporting
- The vulnerability lifecycle and the ticket evidence tied to it
- Building an incident reporting trail auditors can sample
- Getting your ticketing system audit ready
- Where audits break down, and the fixes that actually work
- Pre-audit checklist: what to pull before fieldwork starts
- Why context-rich ticketing quietly reduces audit exceptions
- Turning bug reports into evidence auditors trust
- Sources
What SOC 2 expects from bug tracking and incident reporting
SOC 2 does not name “bug reporting” as its own control category. It maps your ticketing and incident processes to a handful of Trust Services Criteria, and those criteria are what an auditor actually tests.
- CC7.1 covers detecting and monitoring for vulnerabilities and anomalies, including scan cadence and asset coverage.
- CC7.2 covers analyzing and responding to identified security events, which is where your remediation tickets live.
- CC3.2 covers risk identification and analysis, tying severity ratings to business impact.
- CC8.1 covers change management, relevant when a fix requires a code or config change with its own approval trail.
Type I and Type II are not interchangeable. A Type I report evaluates whether controls are designed properly at a single point in time. A Type II examination tests operating effectiveness across a defined window, usually three to twelve months, which means your ticket history has to hold up for every week of that period, not just the week before fieldwork starts. Only a licensed CPA firm can issue either report, and that attestation basis is exactly why auditors probe past the summary metrics into individual ticket fields.
The vulnerability lifecycle and the ticket evidence tied to it
Auditors evaluate vulnerability management as a continuous cycle, not a one-time scan. The six-stage lifecycle auditors expect to see runs like this:
- Asset discovery — an inventory showing what is in scope for scanning.
- Automated scanning — recurring, authenticated scans across that inventory.
- Risk-based prioritization — severity scoring that ties to business impact, not just CVSS defaults.
- Tracked remediation — a ticket for every finding above your accepted risk threshold.
- Verification rescanning — proof the fix actually closed the gap.
- Executive reporting — a summary rolling up SLA compliance and open risk for leadership.
Each remediation ticket needs the CVE or internal identifier, the affected asset, severity, an assigned owner, an SLA deadline, resolution notes, and rescan evidence proving the fix held.
Practitioner benchmark: teams that pass consistently tend to run authenticated scans on a biweekly cadence and hold critical findings to a sub-30-day remediation SLA. Auditors care less about the exact number you pick and more about whether you hit it the same way every cycle.
Building an incident reporting trail auditors can sample
Incident reporting has to survive a sampling test: pull any incident from the period and reconstruct exactly what happened, when, and who signed off. Auditors sample end-to-end, which means every stage needs its own artifact in the ticket, not a verbal summary after the fact.
- Log the incident immediately with a detection timestamp, the detection source (scanner, alert, user report), and who logged it.
- Record severity classification with a short rationale, not just a label, and name the person who made the call.
- Capture escalation steps and notification logs as they happen, in the same system, rather than reconstructed from Slack afterward.
- Close formally with a post-incident review that lists concrete action items and owners.
Pro Tip: Skip the separate “postmortem doc” habit. Auditors want that review artifact linked directly to the ticket, not floating in a wiki they have to hunt down.
Getting your ticketing system audit ready
Most exceptions trace back to ticket configuration, not process failure. Enforce required fields at creation, not as an optional step someone skips under deadline pressure: detection timestamp, owner, severity, SLA deadline, resolution notes, and verification evidence.
Integrating scanners, APM tools, and monitoring directly into ticket creation matters more than any policy document. When a scanner or monitoring tool opens the ticket automatically, the timestamp is trustworthy by construction, and there’s no window for someone to backfill it weeks later.
- Lock timestamp fields so they cannot be edited after creation.
- Auto-attach scan reports and monitoring alerts to the originating ticket.
- Require a linked verification rescan before a ticket can close.
Three reports need to exist for the entire observation period, not just the last month before the audit:
| Report type | What it proves | Sampled by |
|---|---|---|
| SLA compliance | Findings closed within committed deadlines | Auditor spot-checks against ticket dates |
| MTTR (mean time to resolution) | Consistent remediation speed across severities | Trend review across the period |
| Aging by severity | No critical findings sitting open past threshold | Snapshot pulls at multiple dates |
A partner resource on SLA monitoring and remediation tracking covers how teams document these deadlines so the report itself becomes evidence, not just an internal dashboard.
Where audits break down, and the fixes that actually work
The same handful of mistakes generate most exceptions. Backfilled tickets are the biggest one: an auditor spots a ticket created two weeks after the incident actually happened, and the whole chain loses credibility. Missing investigation notes are close behind. A ticket that just says “fixed” with no rationale tells an auditor nothing about the judgment behind the fix.
- Backfilling tickets or approvals after deployment already happened.
- Blank fields on severity rationale or reassignment justification.
- Dashboards showing “passing” access reviews with no per-item decision notes behind them.
- Supply-chain gaps: no gated scans or signed software bill of materials for build artifacts.
Auditors don’t accept green checkmarks as proof of human judgment. They want to see the actual decision written down, even briefly, for access reviews and vendor assessments.
Pro Tip: If you catch a gap late in the observation window, fixing it now rarely saves the current report. Auditors generally want to see at least one clean subsequent quarter before they’ll treat the control as reliable again.
Pre-audit checklist: what to pull before fieldwork starts
Run this before the auditor asks for it:
- Export every ticket from the observation period with timestamps intact.
- Pull linked scan reports for each remediation ticket, matched by identifier.
- Calculate SLA compliance across the full period, not a recent sample.
- Run a self-sample exercise: pick 10 to 15 random tickets and try to reconstruct the evidence chain without touching your compliance dashboard.
- Fix any gap the exercise surfaces before the auditor finds it independently.
A minimal ticket template needs: detection timestamp, source, severity with rationale, owner, SLA deadline, resolution notes, and verification link. An example entry: “Detected 2026-03-14 09:12 via automated scan, high severity (external-facing, unauthenticated), assigned to J. Ruiz, SLA 2026-03-28, patched and rescanned clean 2026-03-25.”
Why context-rich ticketing quietly reduces audit exceptions
Most exceptions come down to thin documentation, not process failure. A ticket that just says “login broken” gives an auditor nothing to sample. Teams that capture the moment a bug happens, screen recording, real-time notes, exactly who found it, build a ticket that reads as evidence on its own.
That’s the practical case for treating detection-to-closure as an evidence pipeline, not a task queue. The gap between what’s written down and what actually happened is where exceptions live.
— Marketing
Turning bug reports into evidence auditors trust
Most teams lose audit time chasing context that never got written down. Wezardapp records the screen and transcribes the issue in real time the moment a tester or reviewer finds a bug, so the investigation notes an auditor wants already exist instead of getting reconstructed from memory weeks later.
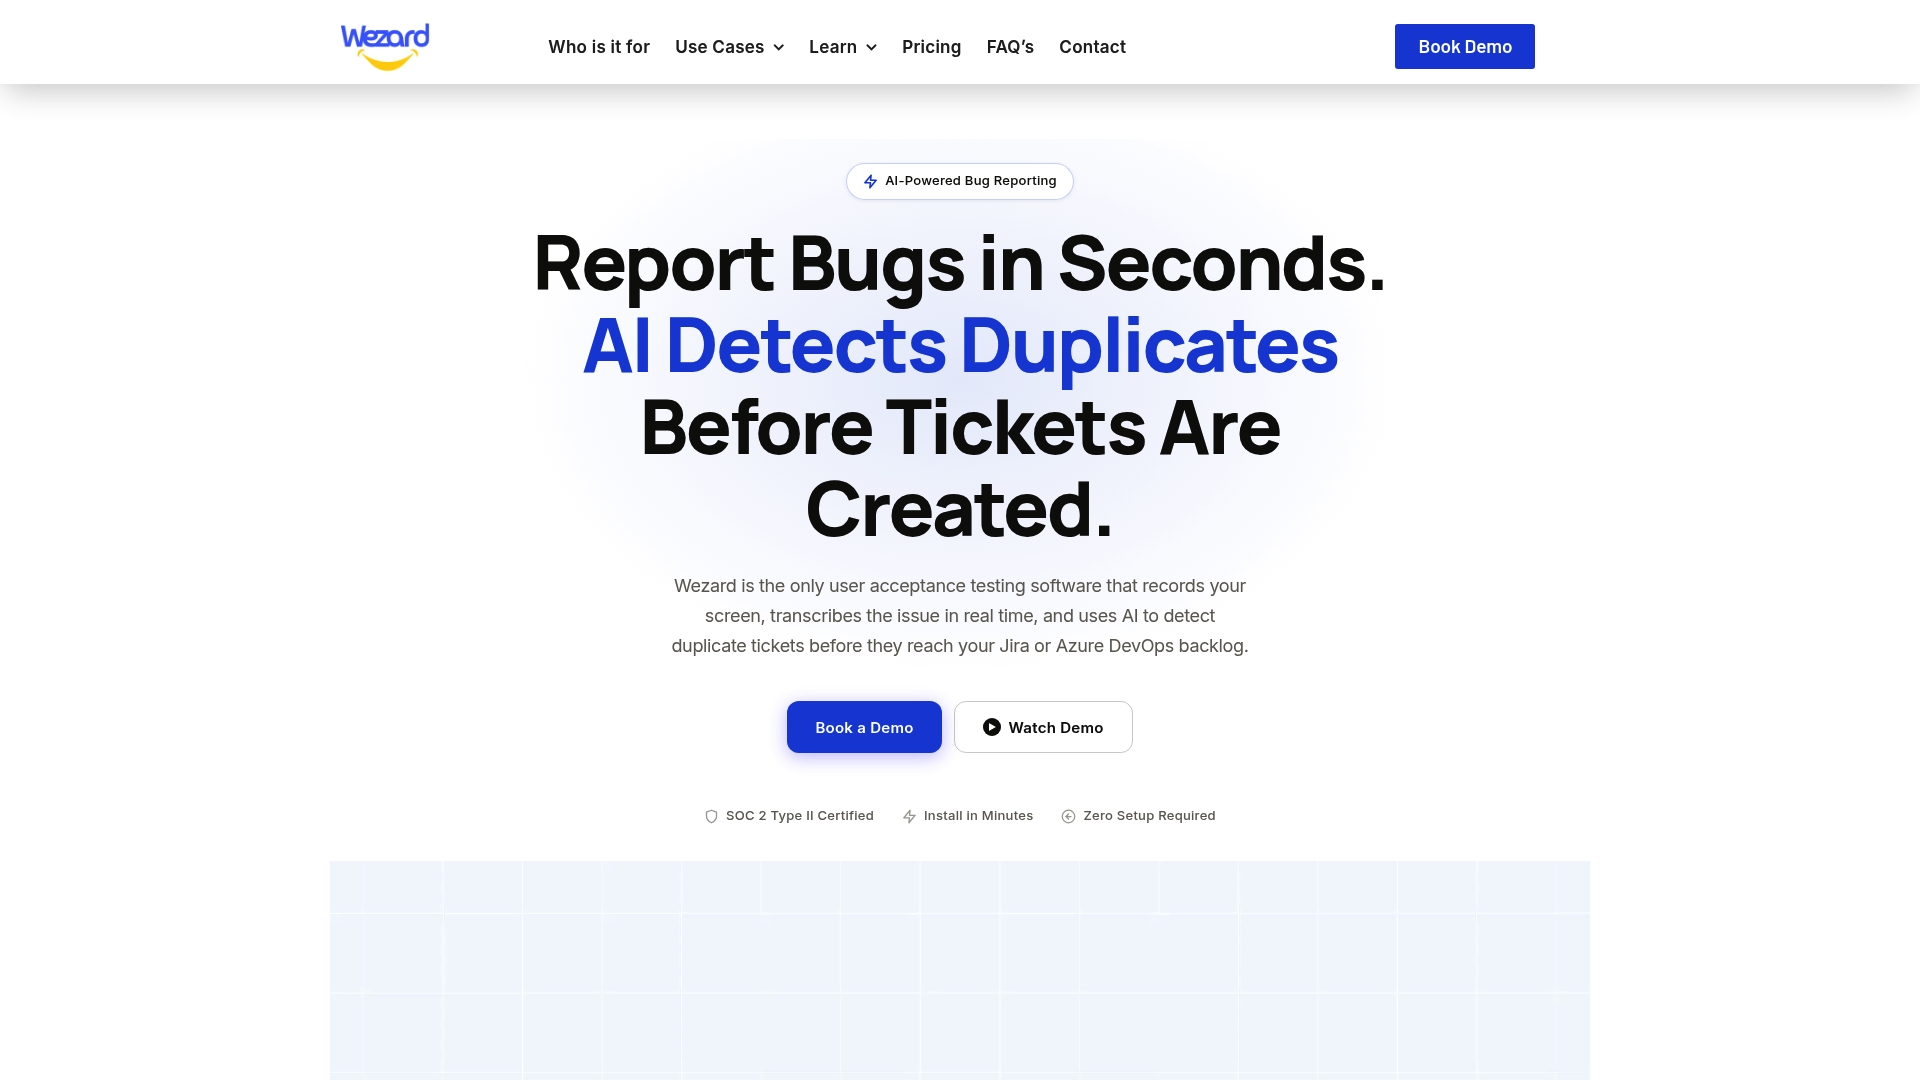
The AI duplicate detection matters here too: it keeps your Jira or Azure DevOps backlog free of redundant tickets, which means the remediation trail an auditor samples stays clean rather than scattered across five duplicate entries with inconsistent timestamps. Because tickets sync directly into Jira or Azure DevOps the moment they’re created, the detection timestamp is set automatically and can’t be backfilled later.
If your ticketing process currently depends on someone remembering to fill in the right fields after the fact, start with a look at Wezard’s bug tracking tool and see what a fully automated intake path looks like for your next audit cycle.
Sources
- Vulnerability management lifecycle for SOC 2 — Josef Kamara
- How to build a SOC 2 incident reporting process — AxiPro
- The developer’s guide to SOC 2 compliance — WorkOS